

With the constantly changing web environment, businesses are now employing advanced anti-scraping tools to defend against unauthorized data access. At Scraping Solution, we see the challenge and the need for responsible, effective, and scalable data fetching. This article discusses how we get past three significant roadblocks of web scraping: CAPTCHAs, bot blocks, and IP bans.
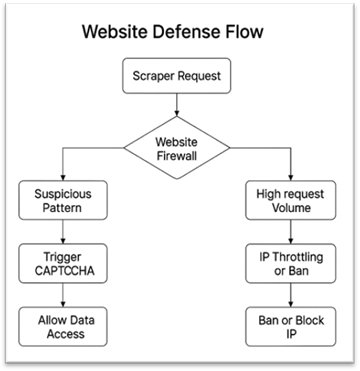
The Challenge: Modern Anti-Scraping Systems
Most sites now have several layers of anti-bot technologies that recognize unusual surfing behaviors. These are the major threats:
CAPTCHAs – Challenges that are meant to distinguish human users from bots.
Bot Detection Systems – Behavioral monitoring software that monitors users' patterns.
IP Rate Limiting & Bans – Prevents access from users with too frequent requests.
Our Solutions: How Scraping Solution Bypasses These Barriers
We deploy multi-layered scraping techniques that guarantee high success rates and quality of data:
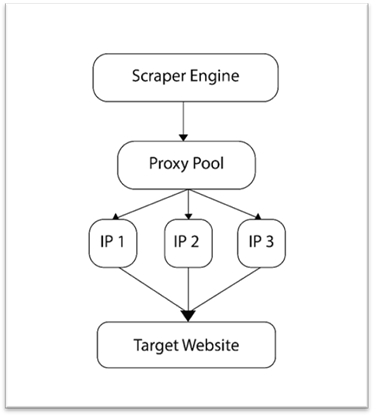
1. Proxy Rotation
Residential & Datacenter Proxies: Emulate human traffic from various geo-locations.
Automatic Rotation: Each request is passed through a different IP.
2. Browser Automation & Headless Browsers
Tools Used: Selenium, Puppeteer, Playwright.
Purpose: Emulate real user activities (clicks, scrolls, mouse movement).
Headless Mode: Executes in the background without UI, conserving resources.
3. CAPTCHA Solving Mechanisms
AI-Based Solvers: Identify and crack simple visual/text CAPTCHAs.
Third-Party Services: e.g., 2Captcha, AntiCaptcha for tough images & ReCAPTCHA.
Human-in-the-Loop: For very rare and bespoke CAPTCHA types.
4. Rate Limiting & Timing Control
Smart Delays: Add random wait times between requests.
Request Patterns: Emulate normal browsing patterns of pagination, slow scrolls.
5. Dynamic Content Handling
JavaScript Rendering: Most sites load dynamically with JavaScript.
Solution: Wait for full content load using Puppeteer/Playwright.
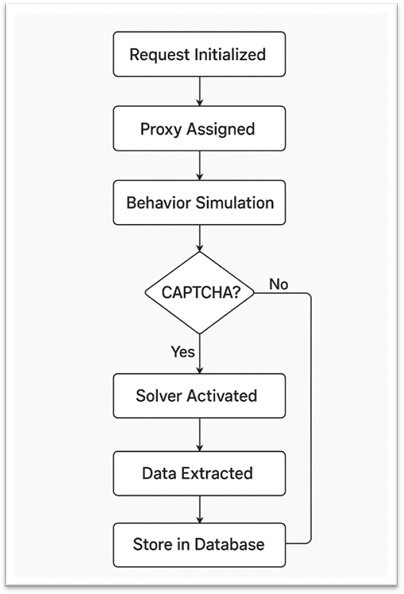
Success Flow: Scraping Through Barriers
Data Accuracy, Compliance & Ethics
At Scraping Solution, we don't merely circumvent barriers - we do so ethically and with transparency. All our scraping projects are governed by the robots.txt protocol of the target site as well as respect data ownership limits. Our first compliance policy prevents us from scraping login-protected or sensitive user data unless specifically permitted to do so. By incorporating strict validation protocols, de-duplication filtering, and automated QA testing, we guarantee that the data we provide not only be timely and scalable but also accurate and 100% trustworthy.
We are committed to data responsibility - marrying innovation with integrity.
Key Benefits of Our Anti-Scraping Solutions
Our solutions achieve a 98% success rate on heavily guarded sites. With scalable infrastructure, we're able to scrape thousands of pages per hour without sacrificing speed or precision. Working in stealth mode with sophisticated mimicry, our scrapers act like real users, making them all but invisible. The result is information that's scraped, not just squeezed out - presented in clean, structured, and ready-to-action formats that enable clients to act right away.
Conclusion
Beating anti-scraping tech is not about brute force but rather smart engineering. At Scraping Solution, we combine cutting-edge tools, ethical strategies, and deep technical knowledge to extract data where others fail.
If your company is built on regular, high-volume web data extraction, reach out to Scraping Solution Ltd today for a no-cost consultation.
Let's unleash the web responsibly.